Confidential (audit firm) · Audit and compliance
An AI agent that reviews reports against a standards dataset and returns clause-level tracked changes a person can verify.
Category
AI
Year
2025
Industry
Audit and compliance
Optimization
Checked before trusted
How it is optimized
Checked before trusted
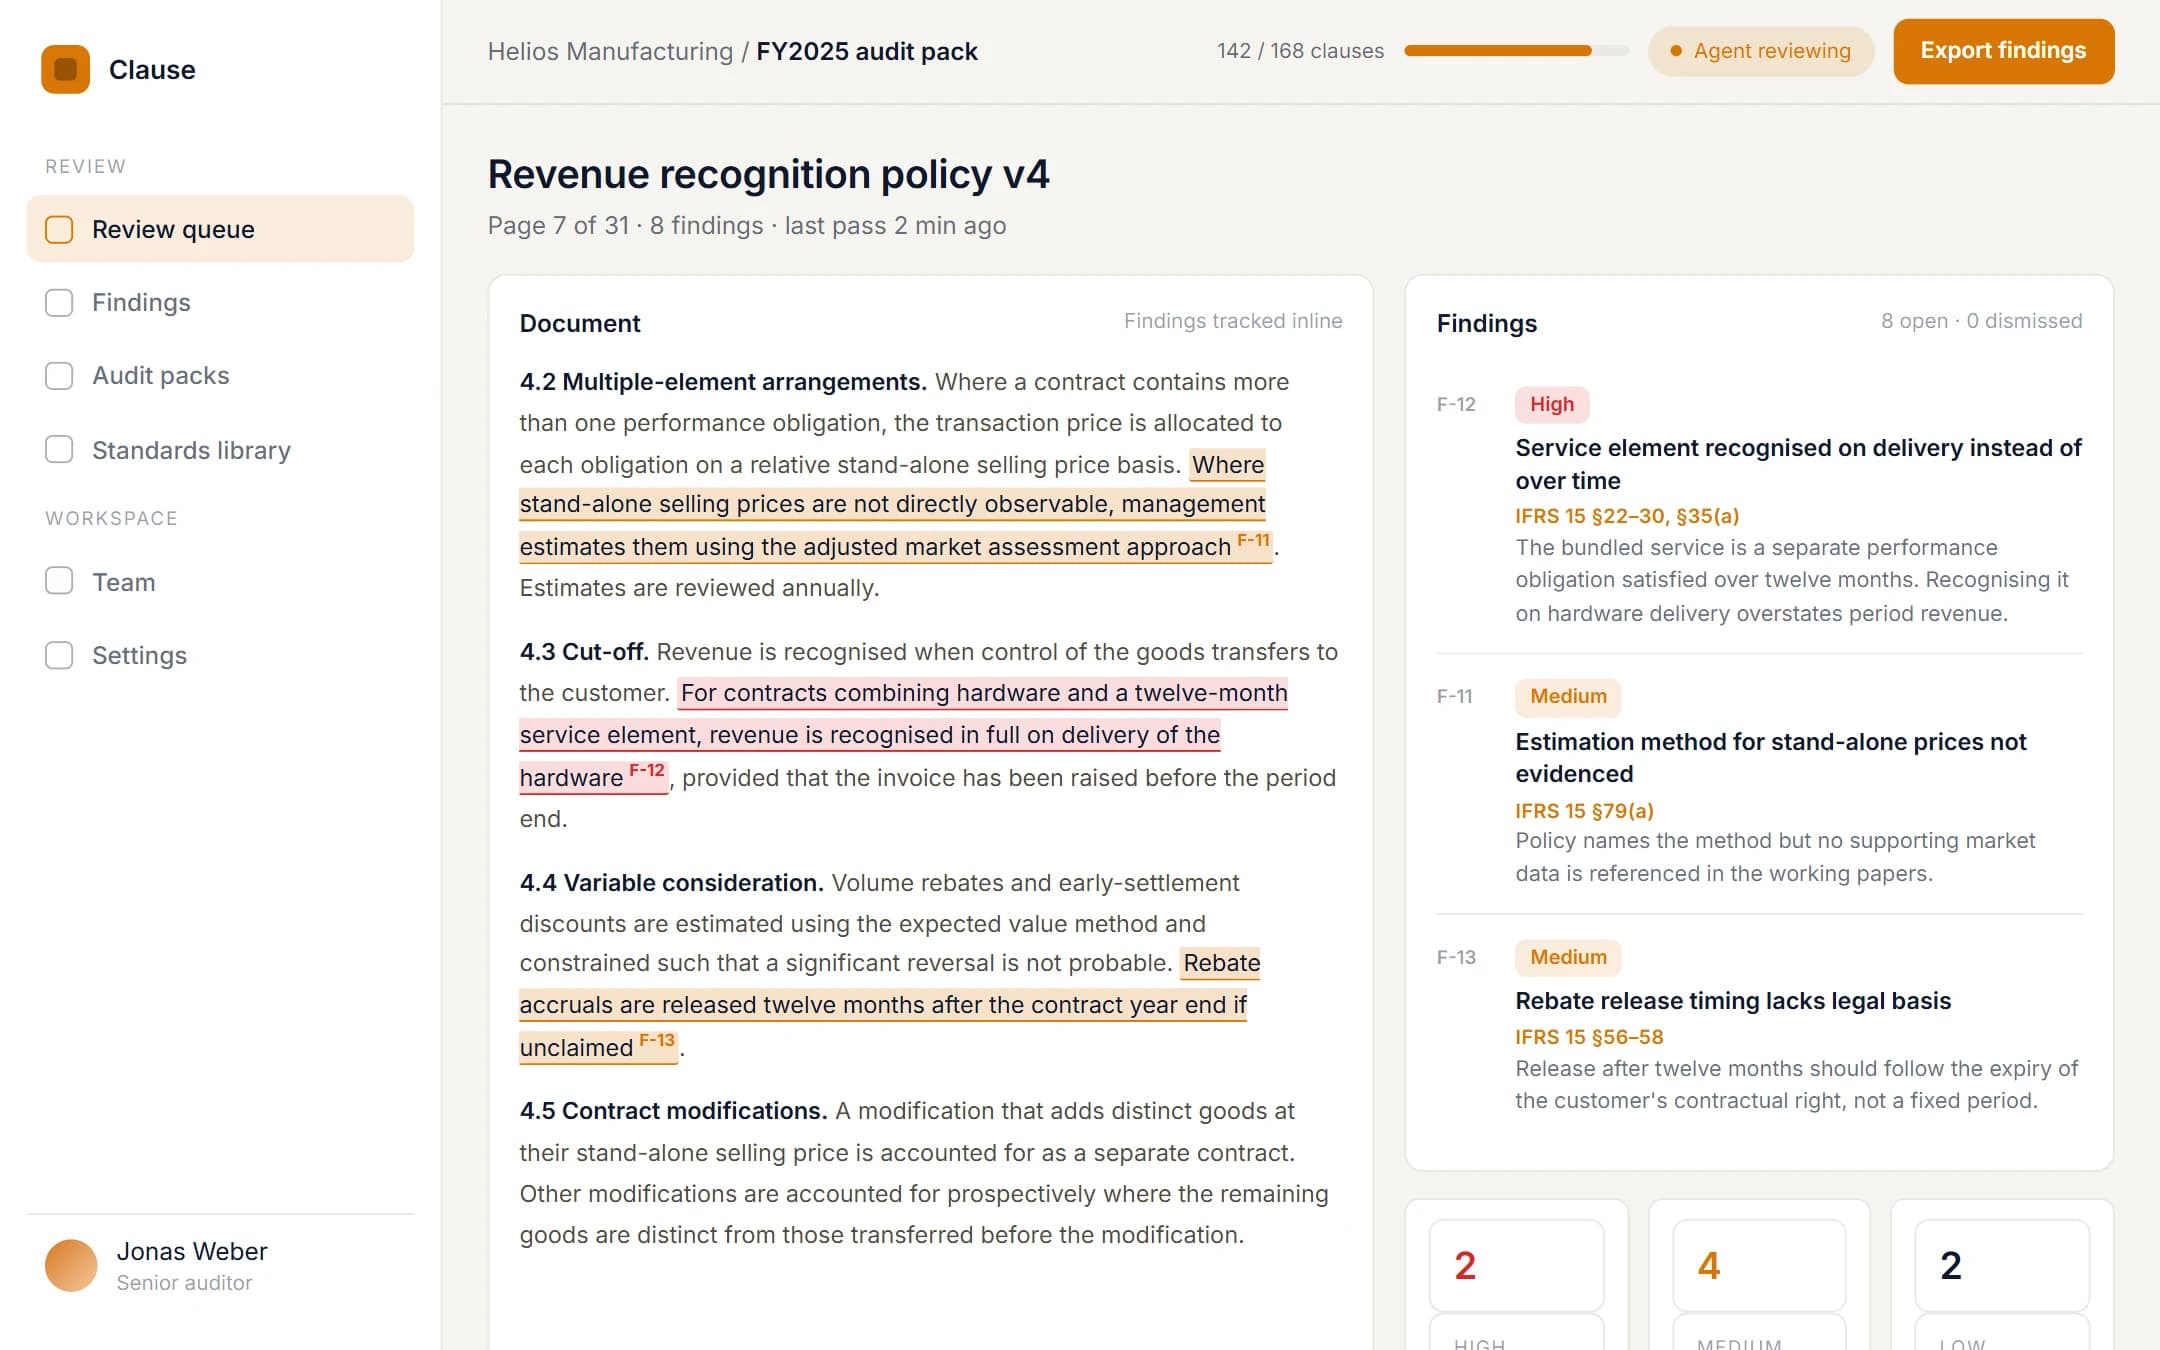
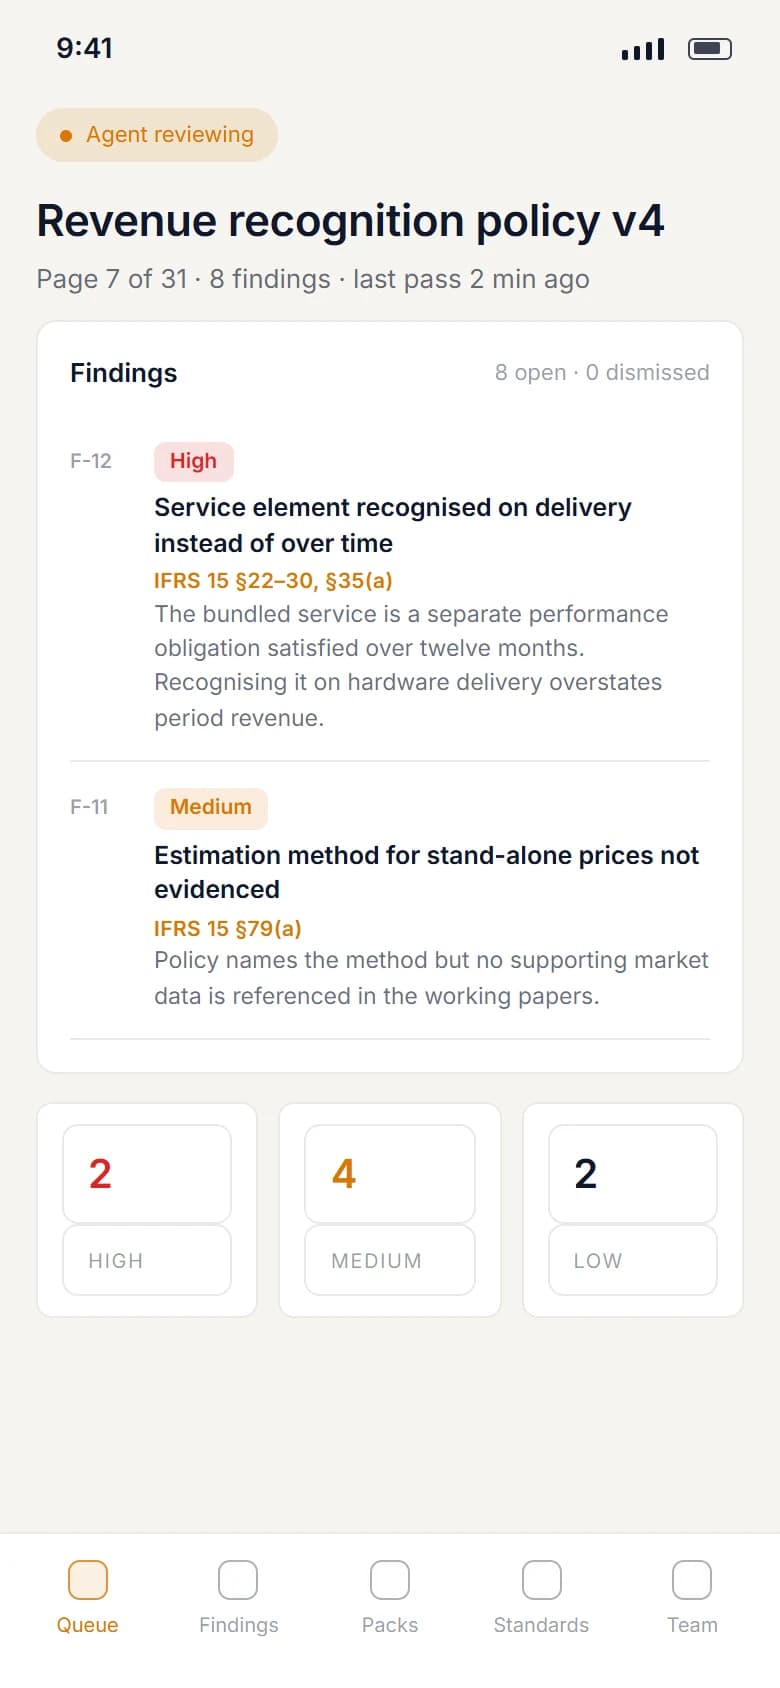
Every finding points at the clause it came from.
Each check is grounded in the standards dataset and returned as a clause-level tracked change with an explanation attached, so a reviewer can verify a finding where it stands. One repeatable workflow evaluates every report against the same standards and output structure.
What keeps it lean
- 01Grounded in a standards dataset
- 02Clause-level, traceable findings
- 03One repeatable review workflow
Output is grounded, traceable or approved by a person where the risk requires it.
The challenge
Compliance and audit reviews against established standards were done by hand. Each report took about a week, and two reviewers could reach different conclusions on the same document. The firm wanted reviews to be faster and consistent, but was rightly sceptical of AI in audit work and would not accept findings it could not verify.
The work
We built an agent that checks uploaded reports against the firm’s standards dataset and returns a findings report as clause-level tracked changes, each with a written explanation and the standard it cites. We started with a small pilot, showed the reasoning behind every finding, and expanded only when the firm’s reviewers were satisfied.
Inside the product
More than one screen.
3 more screens from Compliance Review Agent, captured at device size.
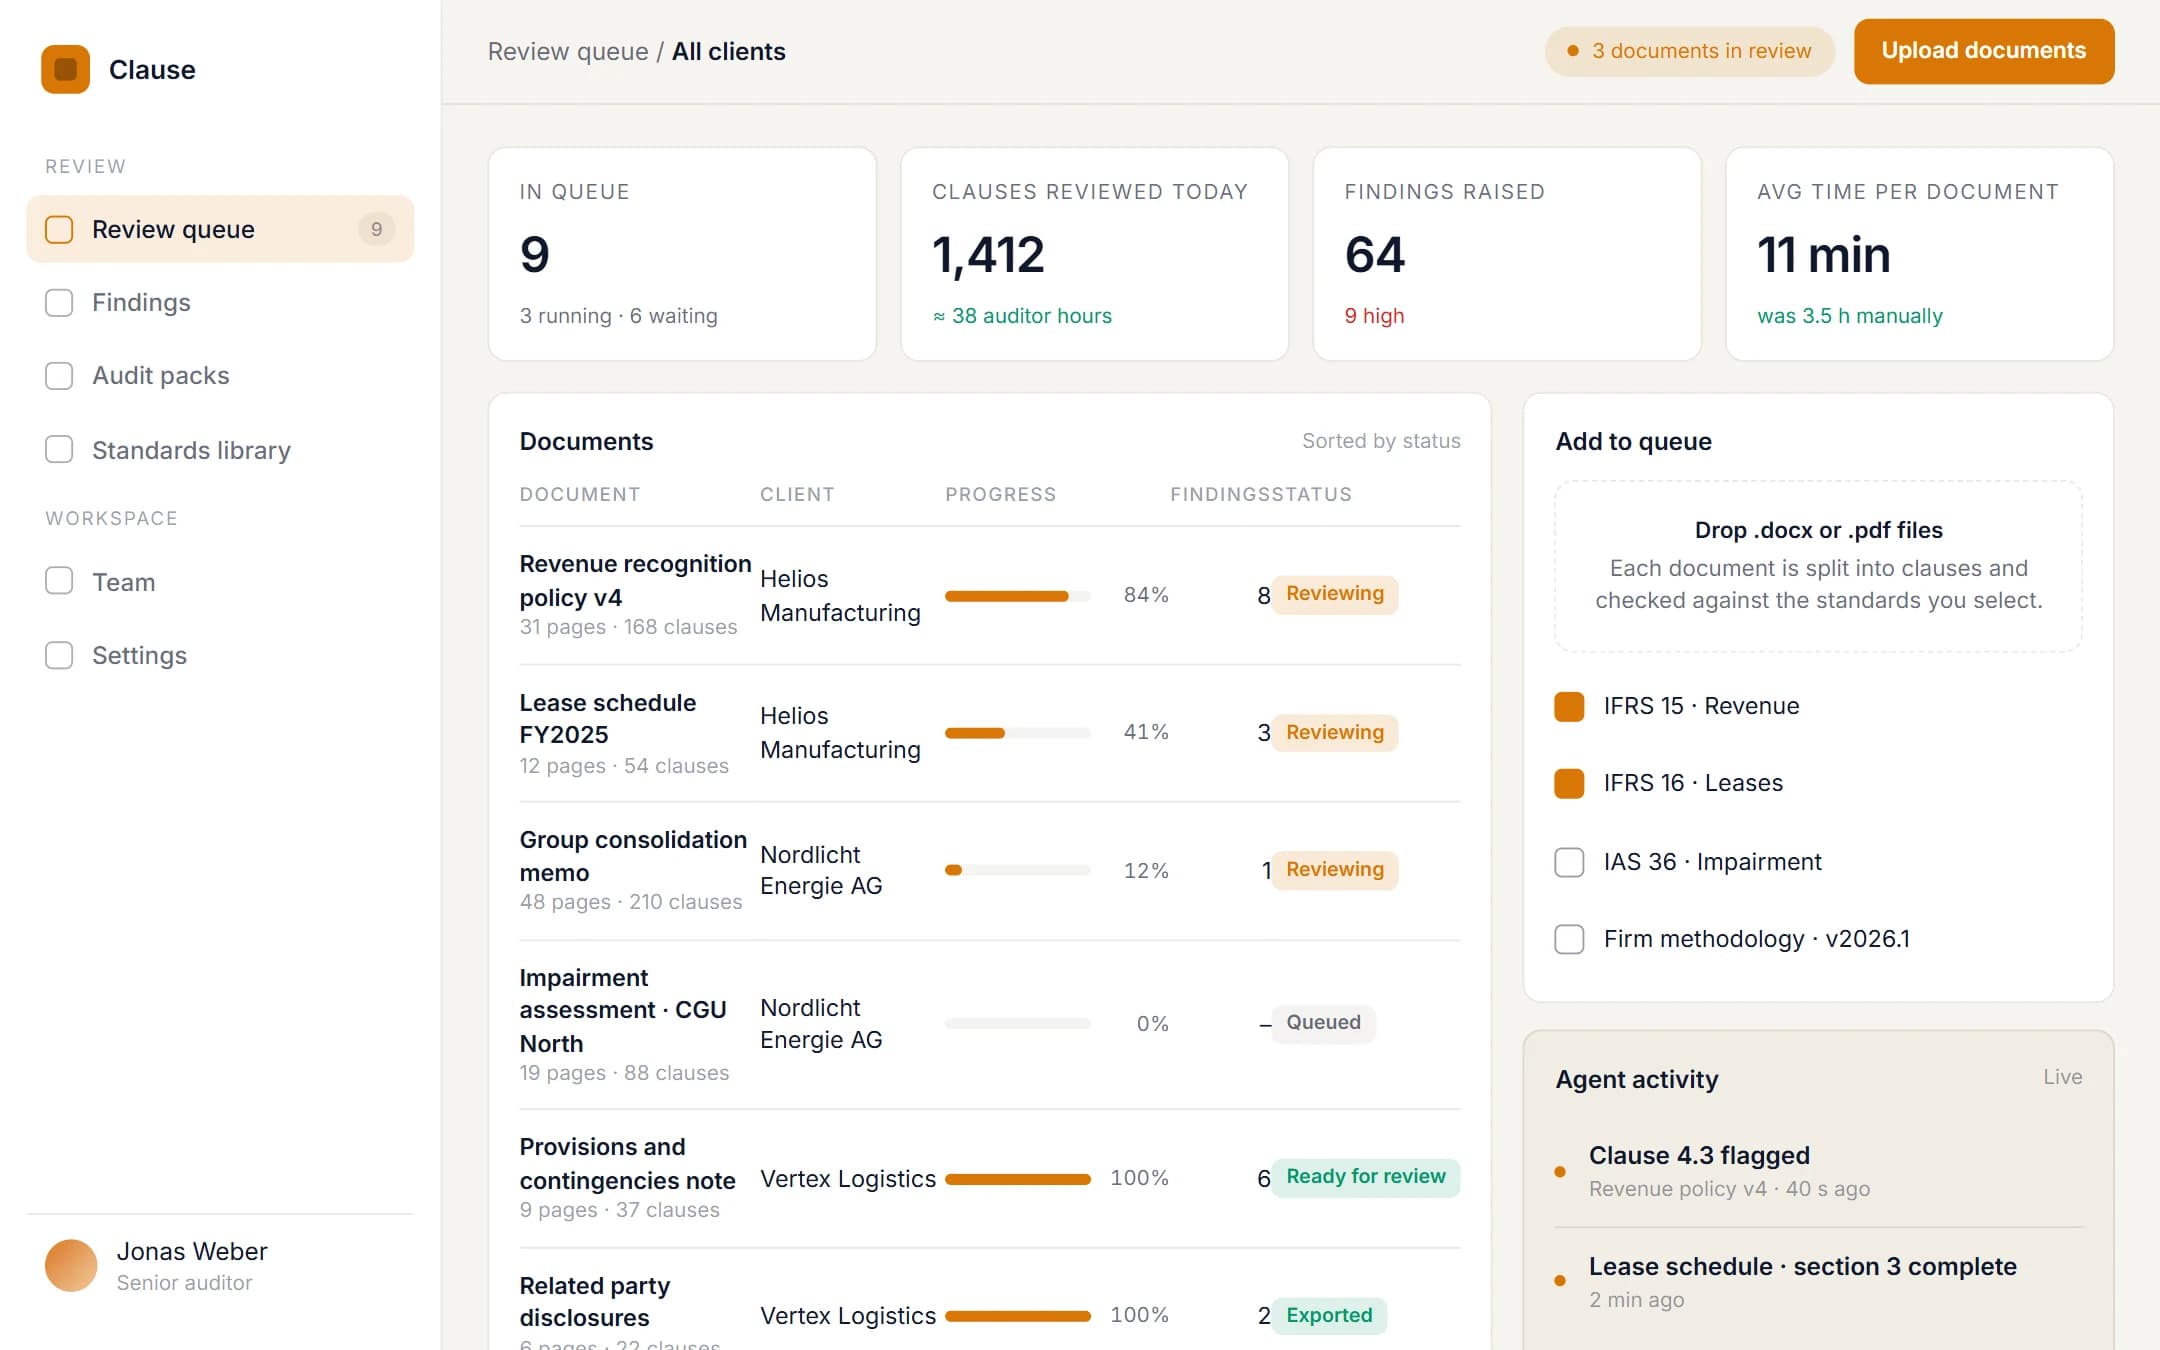
Review queue
Documents split into clauses and checked against the selected standards.
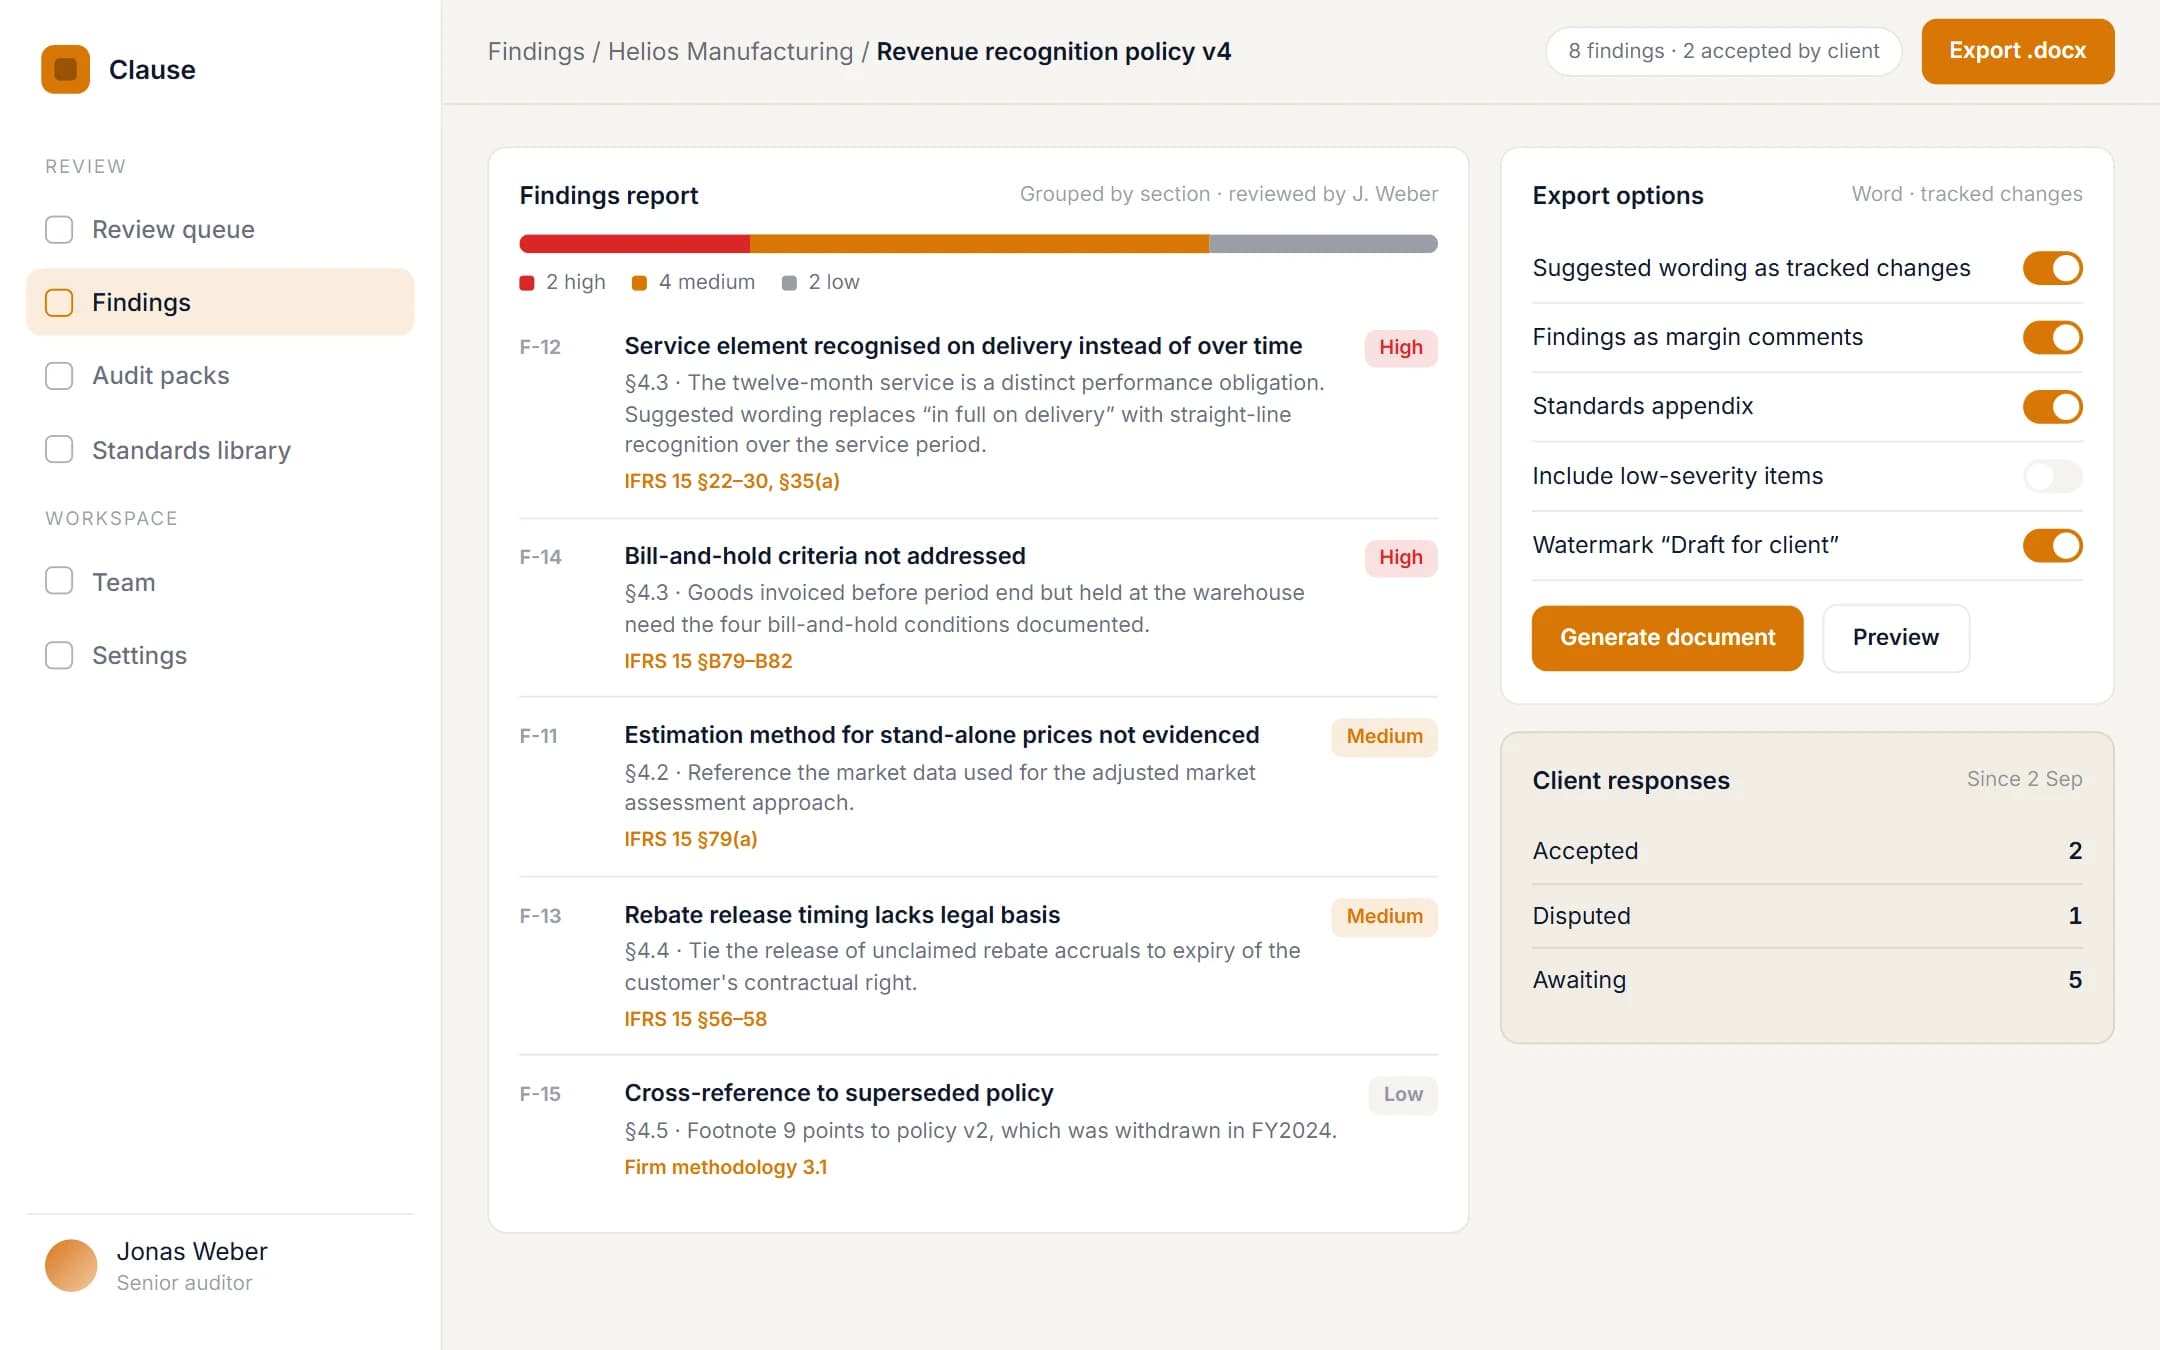
Findings report
Findings by severity, exported as tracked changes and margin comments.
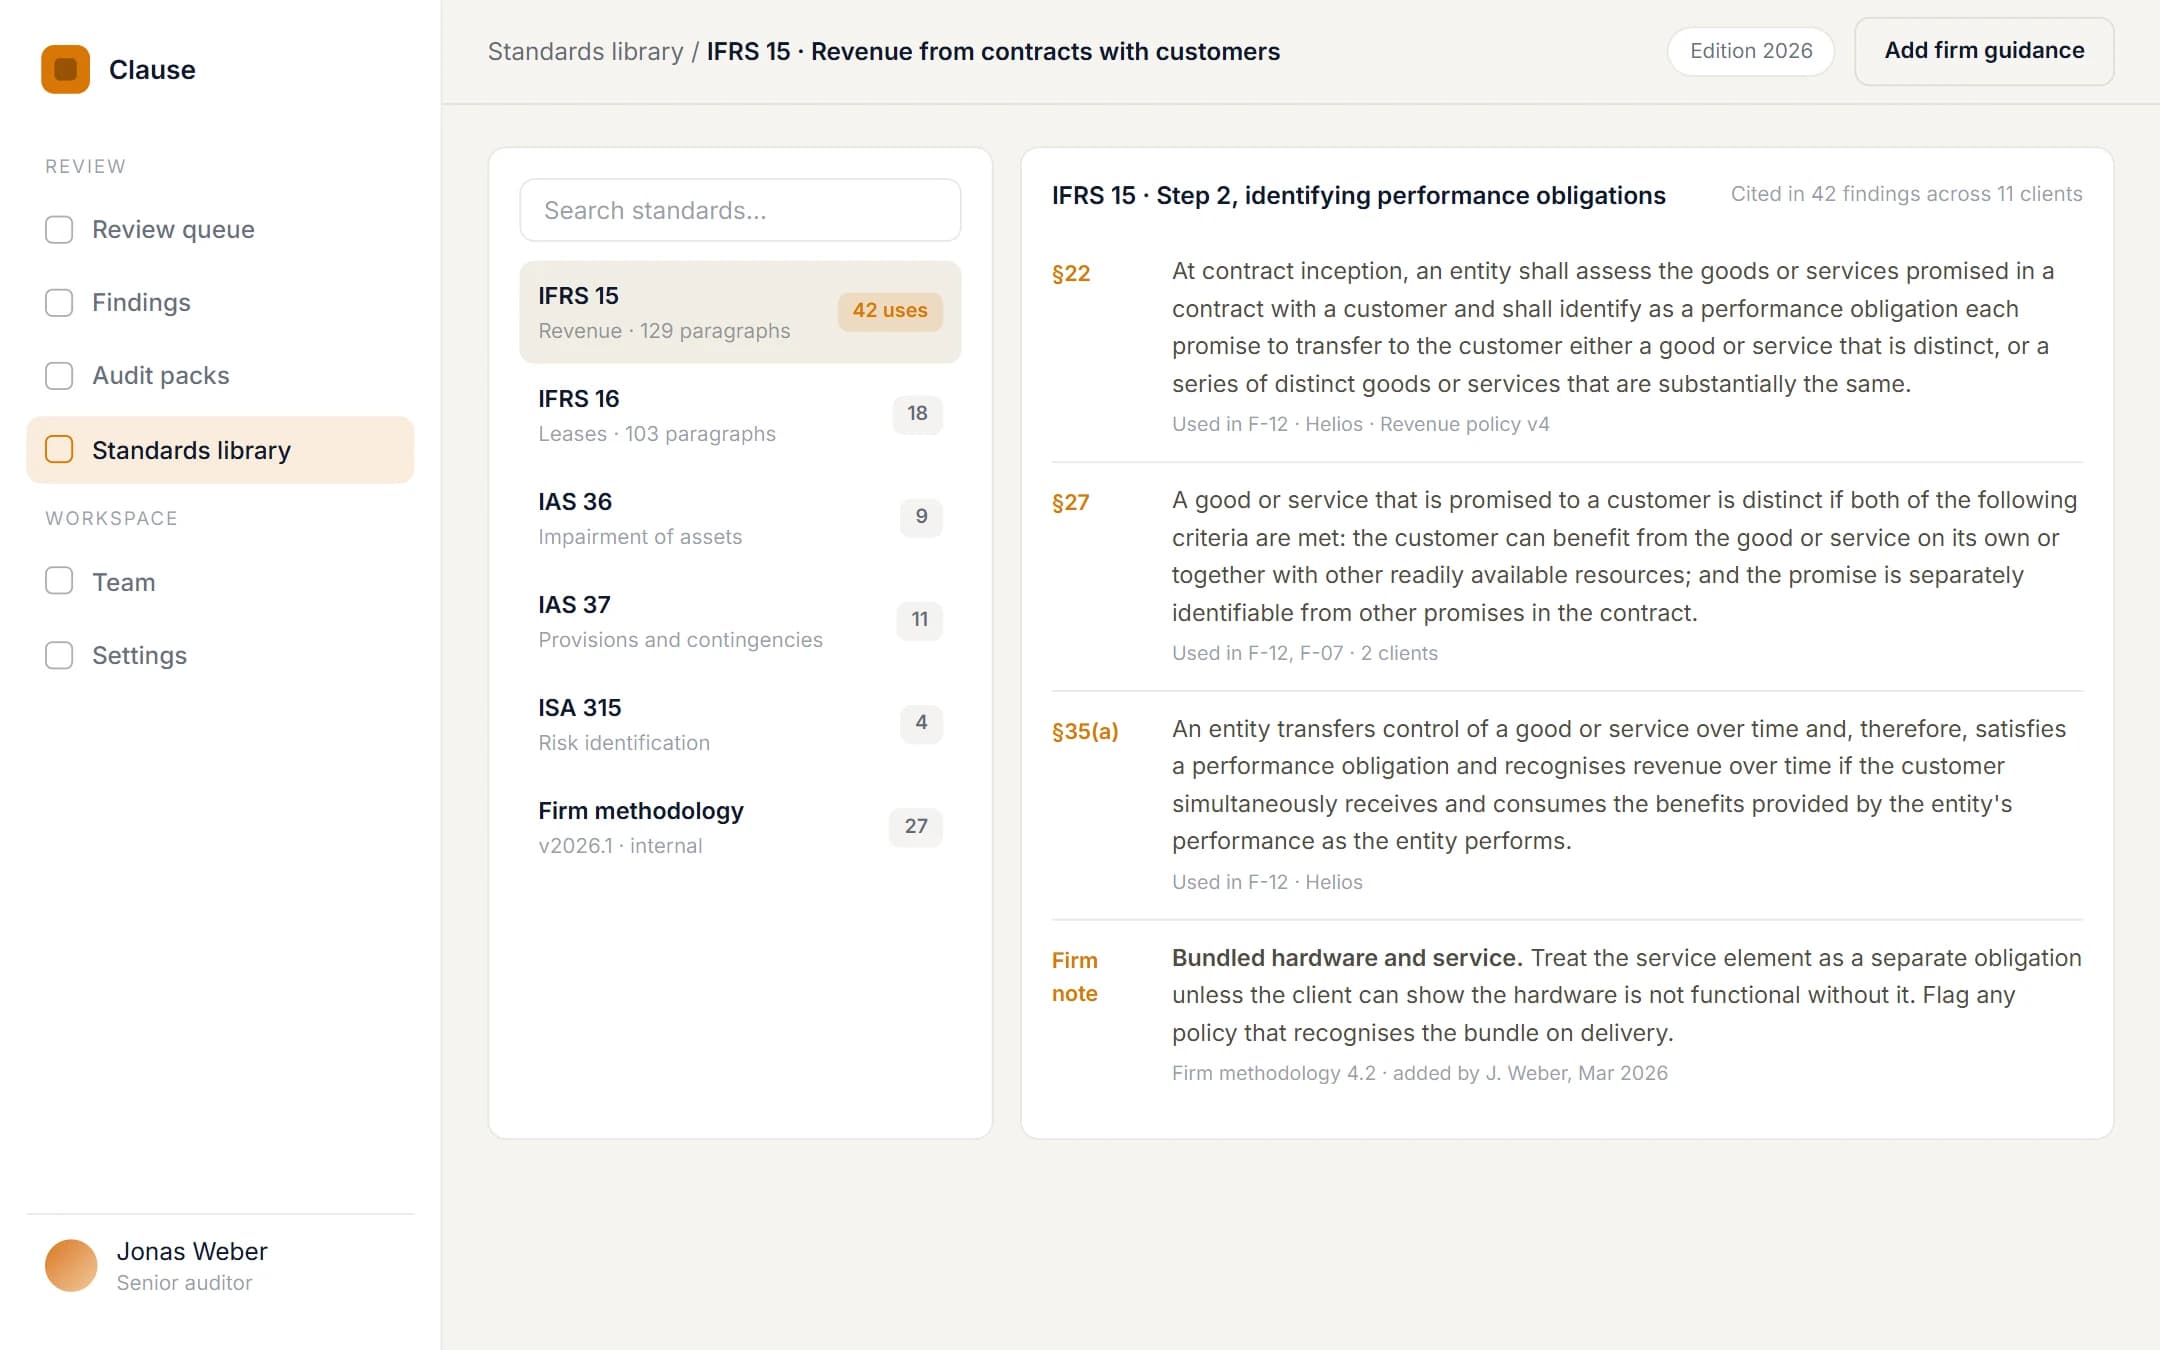
Standards library
The paragraphs every finding cites, with the firm’s own guidance alongside.
On the phone
Home
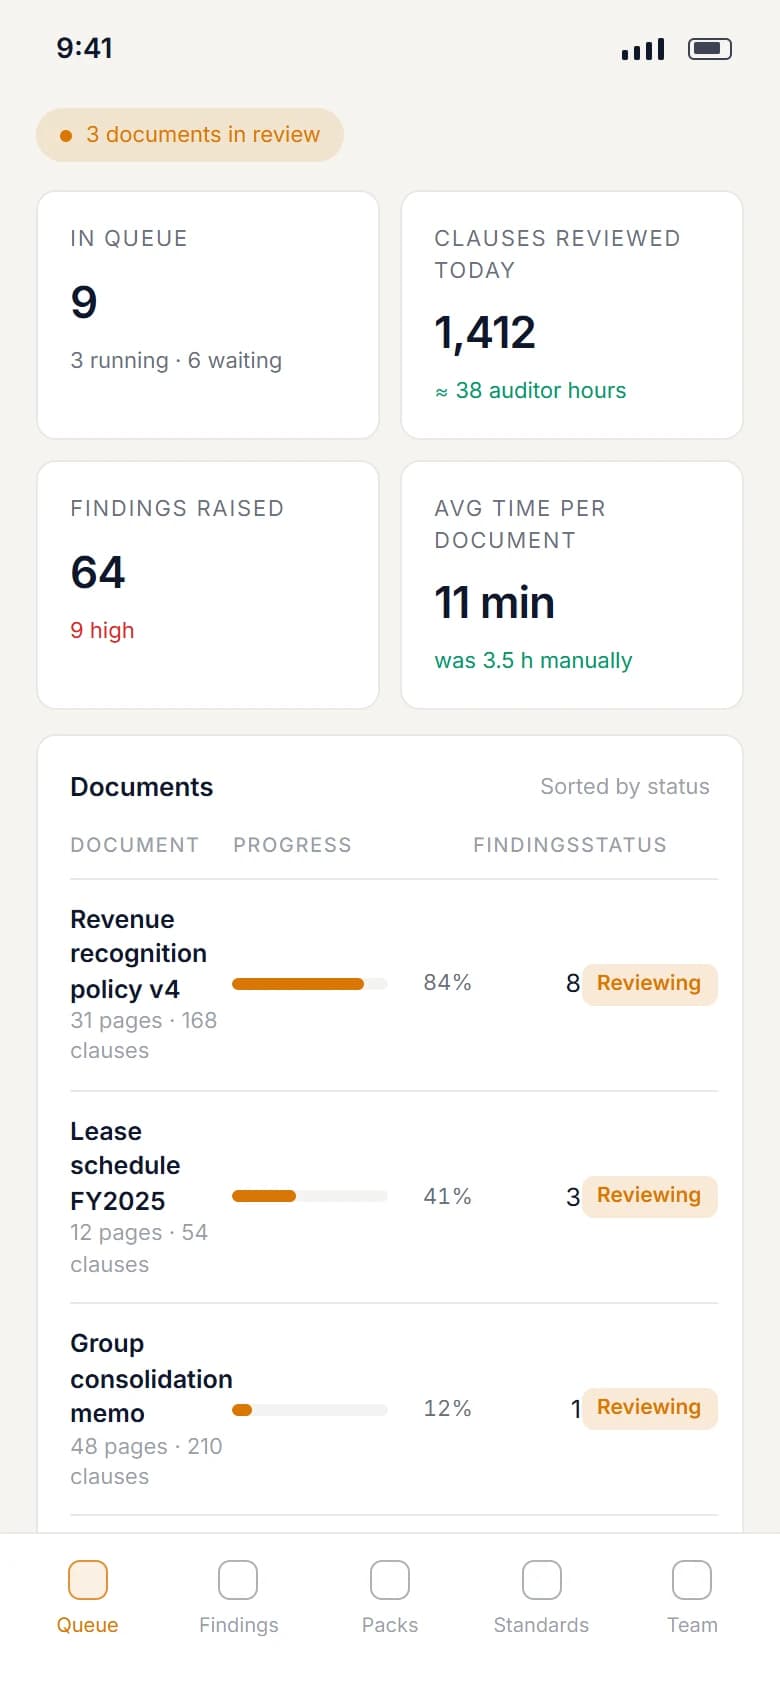
Review queue
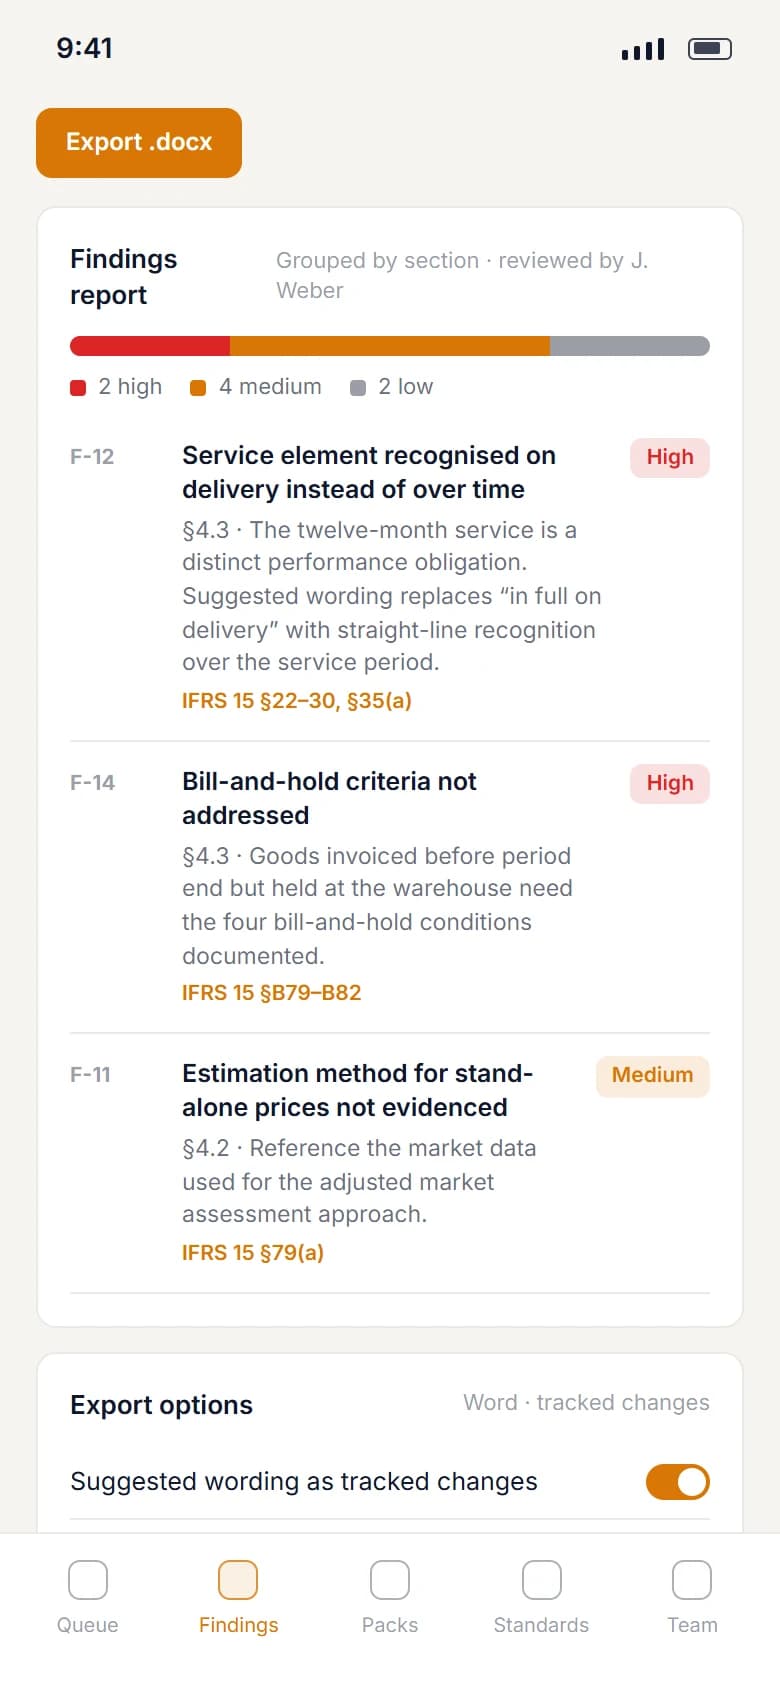
Findings report
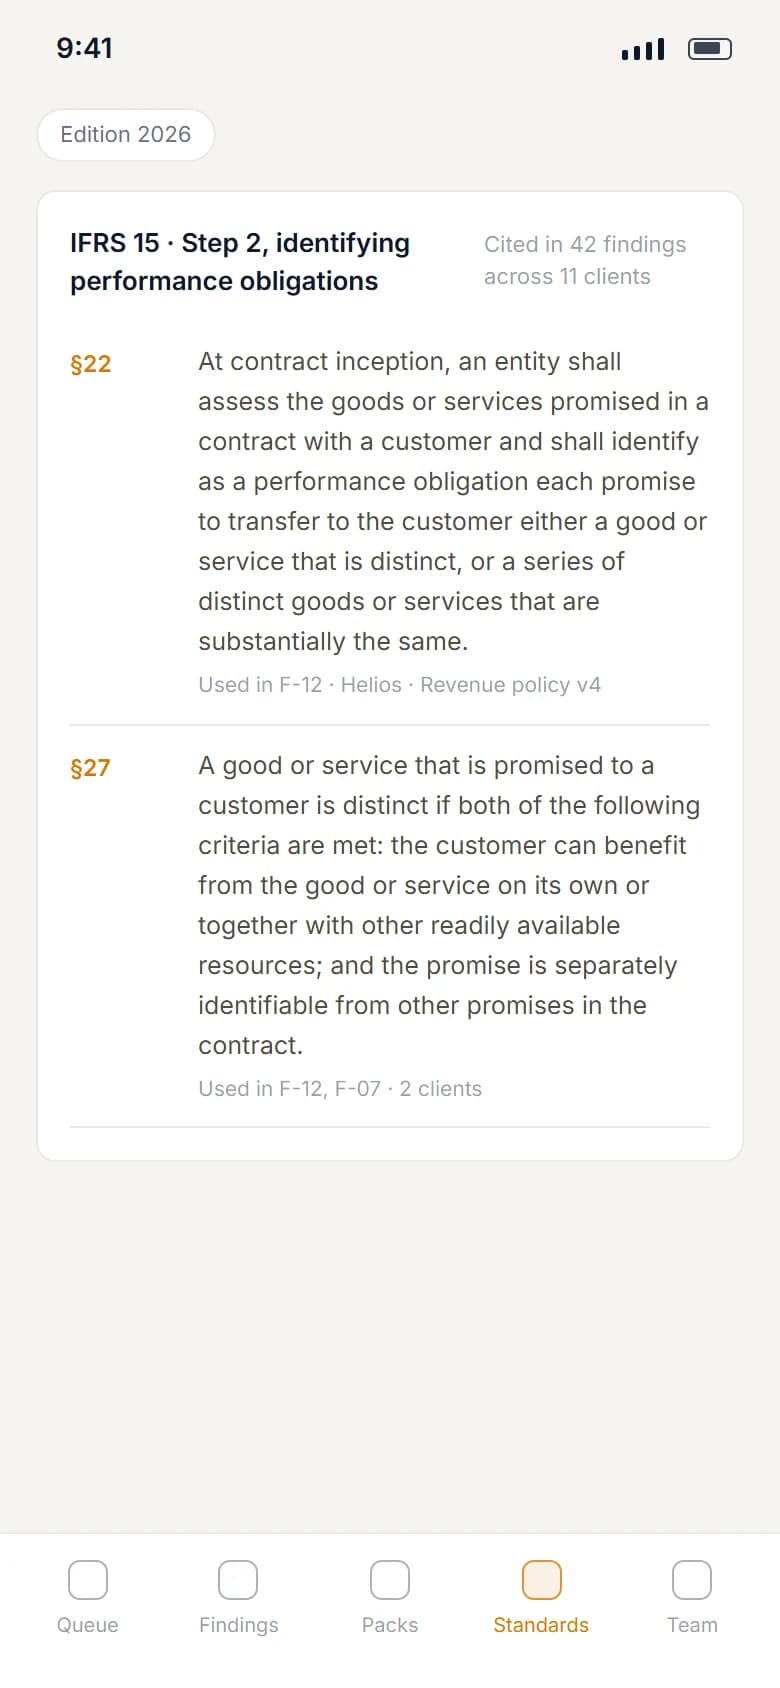
Standards library
How it is built
Architecture
A Python and FastAPI backend deployed on AWS handles report ingestion and comparison against the standards dataset. Claude powers the review and comment generation, returning findings tied to individual clauses for a traceable review workflow.
Key features
Challenges & solutions
Challenge
Broad AI feedback was not precise enough for reviewers who needed to see exactly which clause triggered a finding.
Solution
Grounded each check in the standards dataset and returned findings as clause-level tracked changes with an explanation attached.
Challenge
Reviewer judgement varied between reports, making outcomes difficult to compare and slowing final sign-off.
Solution
Encoded the review as one repeatable agent workflow so every report is evaluated against the same standards and output structure.
The impact
What became easier, better or more effective.
Reviews that took a week now take about half that, and every finding points at the clause and standard behind it. Reviewers spend their time on judgement calls instead of hunting for the paragraph that triggered an issue, and because every report goes through the same workflow, results are comparable between reviewers.
The learning
The pilot doubled as training. Reviewers learned to treat the agent’s findings as claims to check, not verdicts to accept, and the clause-level format made that check quick. Scepticism about AI in audit work turned into a working rule: it is useful exactly where its reasoning can be seen.
“We were sceptical about AI in audit work. They showed their reasoning at every step, started with a small pilot and expanded only when our reviewers were satisfied. Careful, professional, easy to work with.”
2x
faster document review
Turnaround on a compliance report fell from about a week to roughly half, with reviewers still making the final call.
100%
of findings tied to a clause
Each one arrives as a tracked change with the standard it cites and a written explanation, so a reviewer can verify it where it stands.
1
review standard for every report
The same workflow evaluates every document, so results are consistent between reviewers and comparable across reports.
Stack
Backend
- Python
- FastAPI
Cloud
- AWS
AI
- Claude (Anthropic)
Optimization
Checked before trusted
Output is grounded, traceable or approved by a person where the risk requires it.
Conscious AILet's talk
Tell us where you are. We'll say plainly what we would do next, and whether we're the right team for it.